Showing posts with label python. Show all posts

Saturday, July 22, 2017

Expremigen: expressive midi generation

Problem?

A lot of text-based midi specification languages exist, but those I know of suffer from one of the following drawbacks:
  • either the syntax is very low-level as in SKINI, which basically translates all midi events into text. This is great for round-tripping between midi and text, but it's not great for writing and interpreting "manually".
  • or the syntax makes it easy for specifying notes and rhythms but it lacks a way of easily specifying evolution of parameters over time (e.g. crescendos, rallentandos, rubatos, staccatos vs legato). These things are often left as "future work" or they feel like they are implemented as an afterthought and lack in expressive power.

Approach?

I've been working with supercollider a lot lately, and one of its great features is an extensive pattern library. Patterns are like templates for generating music events. After thinking about how to solve the above problems in one easy to use language, I came to the conclusion that supercollider's patterns are an ideal foundation for building a solution.

After some searching I found the isobar library which implements supercollider's patterns in python 2. I noticed some drawbacks in isobar's approach though: it only supports python 2 at the moment, and their patterns appear to be using eager evaluation, meaning that you would not be able to specify patterns with very high ("infinite") repeat counts without overflowing your computer's memory space and exploding the required CPU time. Instead of porting isobar to python 3 I therefore decided to create a new implementation of of supercollider's patterns, based on python generators (i.e. using lazy evaluation), in the expremigen (expressive midi generation library) system.

The next step I took was to couple these patterns with the tweening possibilities found in my earlier vector animation library pyvectortween. By now I had a system that could flexibly animate midi properties like volumes over time.

While creating examples it became clear that writing code might scare off some potential users (especially if you are trying to convert existing music as opposed to generating new music algorithmically) and it was not close enough to my initial goal of creating a new midi dsl (dsl = domain specific language), so I set out to define a syntax and came up with a new midi specification language called MISPEL. MISPEL reuses the best ideas (imho) of  existing systems like lilypond and abc notation and then adds one of its own: property animations. For a more detailed introduction to MISPEL and some examples, please see the github readme file.

What does MISPEL look like? Where's the code?

Please see expremigen's github page for the complete source code of expremigen (Python 3 only, GPLv3 license) and some examples. This is of course a work in progress - despite quite some unit tests, bugs can still be expected, and things might change in the future.

Future?

The language is already quite capable, surpassing other systems in specific areas, and no doubt also lacking in other areas, but perhaps not feature complete yet. For now it concentrates on specifying notes, durations, and animatable properties like volume (crescendo, decrescendo), played duration (staccato, legato), lag (rubato) and tempo (accelerando, ritardando), midi control changes and pitchbend. Other things like program changes and sysex are not supported. Time will tell if and how this system needs to evolve.

One potentially interesting thing would be to somehow base my bluegrass music style compiler on mispel instead of lilypond. I expect this would quickly reveal some of the gaps in the language. 

Another interesting thing could be to investigate reverse engineering of midi files into MISPEL to use as a starting point for adding expressivity.

Tuesday, May 2, 2017

Mask driven vector animations with python

What?

Mask images have many applications. In photo editing, masks e.g. are used to succinctly subscribe where to clip images, or to define regions where an image should be transparant. In video editing, masks are used to describe so-called wiping (fancy transitions from one image to the next). In 3d programs, there's a kind of 3d equivalent of masks, sometimes called dynamic paint, to describe influence of bones on vertices, or to dynamically create vertex colors and displacements.

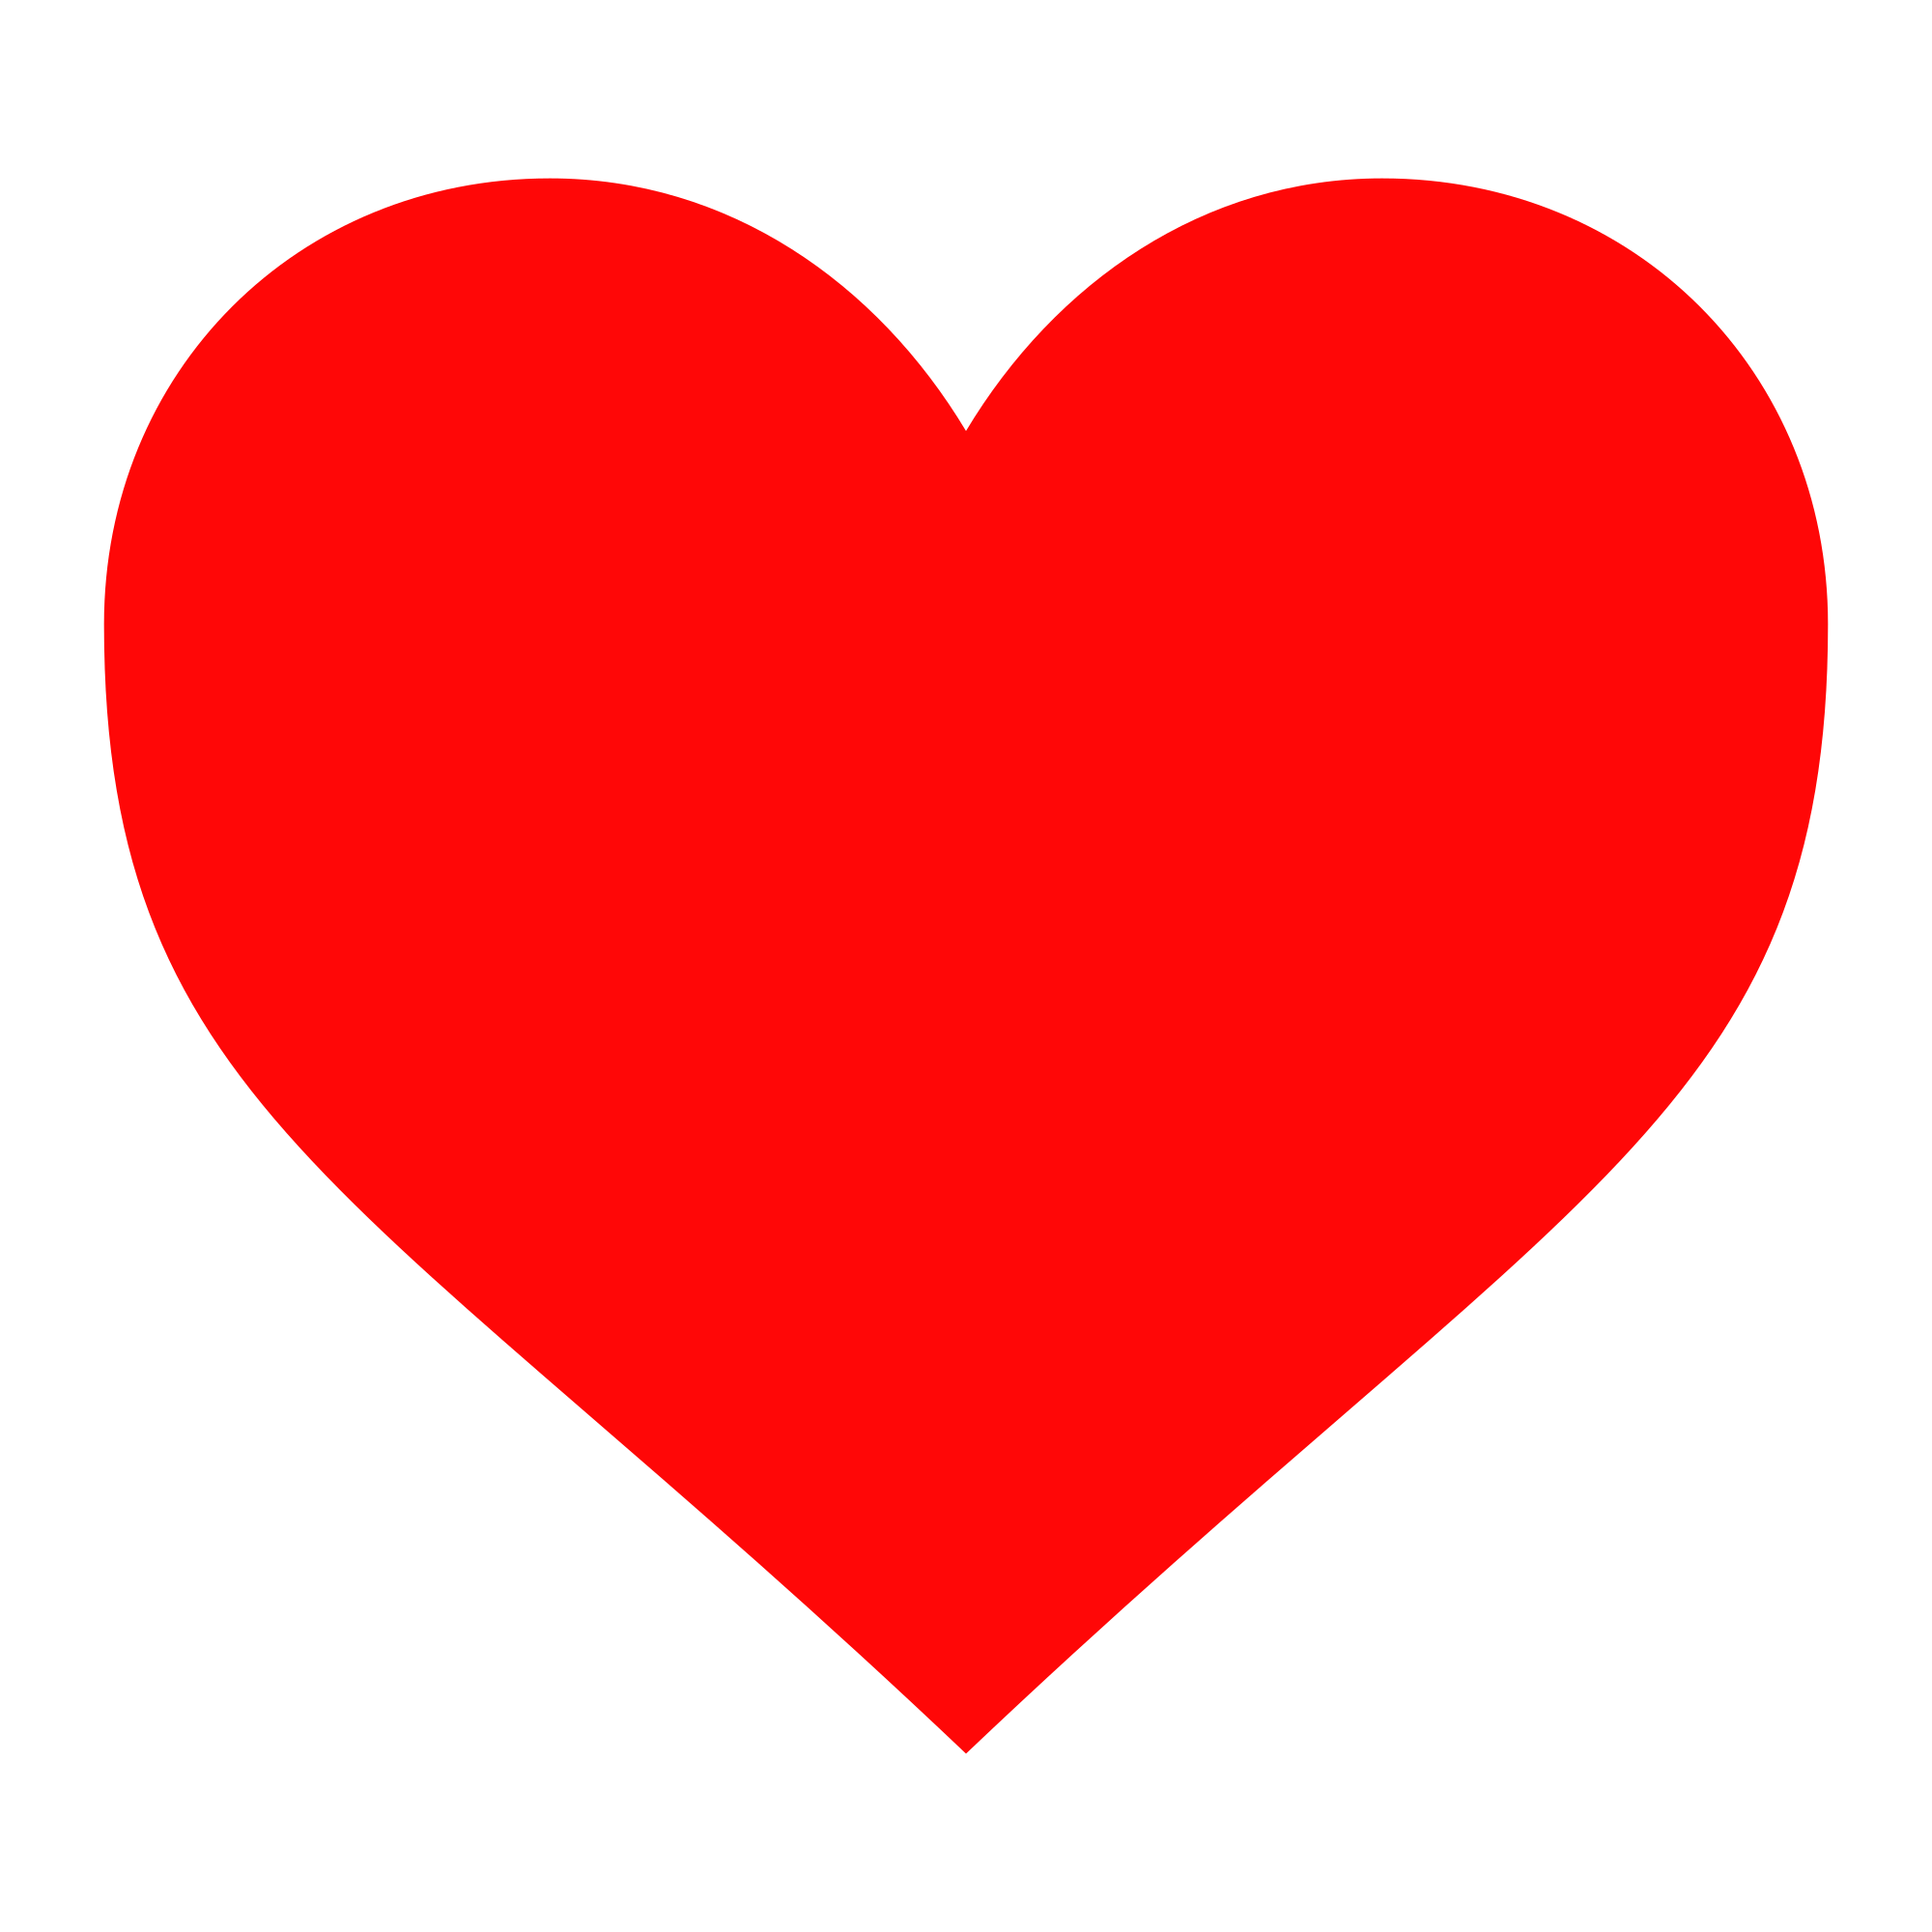
Can we use mask images in combination with vector animation to do some cool stuff? I'd like to think we can. The idea is not to animate the mask image itself, but to interpret the values in the mask image as different animation parameters. E.g. consider the following example of a heart image. The red pixels are considered "masked" pixels, whereas the surrounding transparent pixels are considered unmasked values. Based on whether a pixel is masked or unmasked, we can render different animations. Let's apply the idea on an example to make it more concrete...

I'll use this wikimedia picture as input

And automagically turn it into the following pschychedelic animation


How?


Well. Using the vectortween library and some gizeh and moviepy magic makes this relatively easy.
Here's the code. Sorry it's not particularly short or elegant, and it may need some tweaking with other mask images as input but it shows off the concept.

if __name__ == "__main__":
    import gizeh
    import moviepy.editor as mpy

    from scipy import misc
    from scipy.ndimage import zoom
    from numpy import pi
    from vectortween.NumberAnimation import NumberAnimation
    from vectortween.SequentialAnimation import SequentialAnimation
    import random

    # heart shape retrieved from https: // commons.wikimedia.org / wiki / File: Heart_coraz % C3 % B3n.svg    
    mask = misc.imread("heart.png")
    print("mask.shape = ", mask.shape, " mask.dtype = ", mask.dtype)
    H = mask.shape[0]
    W = mask.shape[1]
    subsample = 20    
    subsampled_mask = zoom(mask, (1 / subsample, 1 / subsample, 1))
    print(subsampled_mask.shape)

    # debug code:    
    # misc.imsave("heart-subsampled.png", subsampled_mask)
    yrange = subsampled_mask.shape[0]
    xrange = subsampled_mask.shape[1]
    xwidth = subsample
    ywidth = subsample
    duration = 5    
    fps = 24

    radii = {}


    def get_color(x, y, subsampled_mask):
        color = subsampled_mask[y][x] / 255        
        return color


    def masked(x, y, subsampled_mask):
        c = get_color(x, y, subsampled_mask)
        if sum(c) > 2:
            return 1        
        else:
            return 0

    def make_frame(t):
        surface = gizeh.Surface(W, H)
        canim = SequentialAnimation([NumberAnimation(frm=0, to=2 * pi, tween=["easeOutQuad"])], repeats=int(duration))
        canim2 = SequentialAnimation([NumberAnimation(frm=2 * pi, to=0, tween=["easeOutQuad"])],
                                     repeats=int(2 * duration))
        radiusmod = SequentialAnimation([NumberAnimation(frm=0, to=10, tween=["easeInOutSine"]),
                                         NumberAnimation(frm=10, to=0, tween=["easeInOutSine"])],
                                        repeats=int(1.5 * duration))
        for y in range(yrange):
            for x in range(xrange):
                if masked(x, y, subsampled_mask):
                    pinkfactor = random.uniform(0.2, 0.8)
                    if (x, y) not in radii:
                        radii[(x, y)] = random.uniform(xwidth / 8, 3 * xwidth / 2)
                    r = radii[(x, y)]
                    modval = radiusmod.make_frame(t, 0, 0, duration - x / 20, duration)
                    if modval is None:
                        modval = 0                    
                    r += random.uniform(0, 3 * modval / 2)
                    gizeh.circle(r, xy=((x + 0.5) * xwidth, (y + 0.5) * ywidth), fill=(1, pinkfactor, pinkfactor, 0.15),
                                 stroke=(1, 0.3, 0.3), stroke_width=1).draw(surface)
                else:
                    alphafactor = random.uniform(0.2, 0.8)
                    endpoint = canim.make_frame(t, 0, 0, duration - y / 20, duration)
                    endpoint2 = canim2.make_frame(t, 0, 0, duration - x / 20, duration)
                    if endpoint is not None:
                        gizeh.arc(xwidth / 2, 0, endpoint, xy=((x + 0.5) * xwidth, (y + 0.5) * ywidth), fill=None,
                                  stroke=(1, 1, 1, alphafactor), stroke_width=2).draw(surface)
                    if endpoint2 is not None:
                        gizeh.arc(xwidth / 4, 0, endpoint2, xy=((x + 0.5) * xwidth, (y + 0.5) * ywidth),
                                  fill=(0, 1, 1, alphafactor),
                                  stroke=(1, 1, 1, alphafactor), stroke_width=2).draw(surface)
        return surface.get_npimage()


    clip = mpy.VideoClip(make_frame, duration=duration)
    clip.write_gif("example_heart1.gif", fps=fps, opt="nq")

Where can I find this magic vector tween library?


Glad you're asking! All the magic can be found here.

I'm curious to see what advanced animations you can come up with using a mask driven vector animation technique. Note: to add more layers of omgwow!!! nothing stops you from animating the mask image as well, or from generating the mask images programmatically. Or maybe you can go recursive.... how about you use the heart animation frames as animation masks for yet another, perhaps even more psychedelic animation?

You can also watch and listen to my recent music video "The Vows" that embeds vector animations generated using pyvectortween here:


Monday, May 1, 2017

Tweened vector animations in python part II

What?

This is a continuation of part I on creating vector animations with python. In recent days, the library has seen the addition of many new features: 
  • animations along paths defined by symbolic parametric equations
  • animations along Bezier curves defined by control points (any order)
  • animations defined by equations in polar coordinates
  • composing animations into sequential and parallel animations
  • all animations now support getting a list of curve points for displaying the paths
And all of the new animations also still support tweening of course!

Show me! Show me!

The following picture shows a sequential animation of a cubic and a quadratic bezier segment, displaying the path, and using an easeOutBounce tweening on both segments.


The above picture is generated by one of the included examples in the vectortween library.

Sunday, April 23, 2017

Tweened vector animations with python

What?

In this blog post I'll show how to create tweened vector animations with python. People who arrive here probably ought to look at Zulko's excellent blog post first to find the excellent gizeh library, written on top of cairo, that allows for generating vector graphics animations in python. And then there's also Zulko's wonderful moviepy library that allows saving these animations to animated .gif or one of the many video formats supported by ffmpeg.

While experimenting with Zulko's libraries, I was struck by what seemed a missing feature: a convenient way to introduce "easing" in animations. I subsequently found the pytweening library which implements the formulas required to perform easing and created my own vectortween library to wrap pytweening and make it usable in combination with Zulko's libraries (as well as other libraries).

How?

Here's some sample code using plain gizeh. It creates a yellow circle moving from the top left to the middle of the drawing:

if __name__ == "__main__":
    import gizeh
    import moviepy.editor as mpy

    W, H = 250, 250  # width, height, in pixels
    duration = 5 # duration of the clip, in seconds
    fps = 25

    def make_frame(t):
       # prepare a drawing surface
       surface = gizeh.Surface(W, H)

       # as time t evolves from 0 to 5 seconds, calculate new position of
       # the yellow circle
       gizeh.circle(30, xy=((t*22),(t*22)), fill=(1,1,0)).draw(surface)
       return surface.get_npimage()

    clip = mpy.VideoClip(make_frame, duration=duration)
    clip.write_gif("example0-plain.gif", fps=fps, fuzz=10)

And what does it look like?

Boring, right?

Now how about you wanted add some excitement by letting the yellow circle bounce a bit upon arrival in the middle of the picture? Are you ready to write out the math formulas to do so? If yes, by all means go ahead! If no, you could try the vectortweening library to write this:

if __name__ == "__main__":
    import gizeh
    import moviepy.editor as mpy

    from vectortween.PointAnimation import PointAnimation

    W, H = 250, 250  # width, height, in pixels
    duration = 5 # duration of the clip, in seconds
    fps = 25

    def make_frame(t):
        # prepare a drawing surface
        surface = gizeh.Surface(W, H)

        # p animates from position (0,0) to position (110,110) with an
        # easeOutElastic tweening method
        p = PointAnimation((0, 0), (110, 110), tween=['easeOutElastic', 1, 0.2])

        # circle to appear at second 0.2, animate from second 1 to 4,
        # then stay visible until disappearance in second 5
        xy = p.make_frame(t, 0.2, 1, 4, 5)

        # because graphics can disappear, we must check for None
        if None not in xy:
            gizeh.circle(30, xy=xy, fill=(1,1,0)).draw(surface)
            return surface.get_npimage()

    clip = mpy.VideoClip(make_frame, duration=duration)
    clip.write_gif("example0-tween.gif", fps=fps, fuzz=10)

And what does it look like?


We want more, we want more...

Ok, ok... I hear you. Here's another one:


Ooooh I need this now!

Well of course you do... Here's all you need!

Monday, July 8, 2013

Automatically create a GUI for your argparse based command line tool

Problem

You are asked to create small tool in python to help someone out. Someone else comes along who wants to reuse the tool, but needs a minor variation on the theme. No problem, you think, I'll just add a command line option using python's argparse module.

Fast forward one month. The tool proves to be a success, but everyone wanted something slightly different, leading to 15 command line options. Now people start to complain that they lose oversight over the command line options. Other people see the potential in your tool but they are afraid of command lines altogether...

You realize you could please your users by giving them a UI to set up the command line options. But creating a UI is a lot of work... What now?

Argparseui to the rescue!

If you think you may get away with a zero-effort but ugly auto-generated UI, perhaps argparseui (python2.7 and python3, GPLv3) can be of use. Argparseui depends on PyQt.

As of yet it doesn't support all of argparse, nor does it officially support python3 (although basic use cases seem to work with python3), but it seems to scratch my itch.

Example code?

 Using argparseui is very similar to using argparse. Here's an example:

Screenshot?

This is a screenshot made on Linux, IceWm. On windows, the dialog will look like a windows dialog, and on Mac OsX it should look like a Mac OsX dialog...

Sunday, April 21, 2013

Algorithmic composition with python, rtmidi, yoshimi, linuxsampler

What?

Generating real-time midi events from python!

Why?

For fun! Dabbling with python and algorithmic composition.

How?

Unpolished code available from github: Twenty five shades of random.

Eh?

Ok, ok, here's the manager's summary. Really, you should check out the code for all the details.

A score is made by scheduling activation and deactivation of score generators in time.

Score generators consist of a strategy (e.g. pick random notes and add random octaves to them, and choose random velocities, and ...) and constraints (e.g. the notes must come from a given list of allowed notes, the durations have to be a multiple of pi, ...).

There's a scheduler class that for any given time can tell you what score generators are supposed to be running or stopped. More philosophy and background information for this piece can be found on my music blog: A Touch of Music.

Youtube movie with the result of running the program once:

Each time you rerun the program, you get a different composition in a very similar style.

Creation of this piece was heaps of fun! For further experiments in algorithmic composition (if any!) I probably owe it to myself to check out in some detail the promising supercollider environment.

Friday, June 1, 2012

Learning to read music notes faster

The Problem

I love to learn new music, but I experience difficulty reading notes that lie high above or below the staff fast enough. Being into programming I thought I'd create something to help me, and while doing so learned some neat things.

Requirements

  • I imagine a kind of flash card system: a program that displays random music notes, lets me guess the note names and then tells me how long it took to finish all the assignments as a simple way of tracking my progress in reading notes faster.
  • I want to be able to configure which notes I'm questioned about: one day I may want to practice low notes, another day I want to practice high notes. And I can imagine beginning musicians would be happy to practice "easier" notes as well.
  • The system should support at least the g-clef and the f-clef (the two most commonly used clefs).
  • To quickly reach some result, I want to prerender all the graphics. This also allows me to use software to generate professional looking graphics. The icons that go on the buttons must be automatically generated too, as I'm not interested in manually creating and maintaining icons.
  • Finally, I want the program to run on at least linux and windows systems. I don't have a Mac to test on, but preferably it should be easily portable to Mac's too.

Technology choices

  • The program is written in python 2.x and pyqt4. The code is available under GPLv3 license.
  • To create the graphics
    • I first programmatically generate lilypond files.
    • I then render those .ly files to scalable vector graphics (svg) format. Display of the assignment can immediately use the .svg format. SVG being a vector format, this will ensure maximum quality.
    • The icons on the buttons to the best of my knowledge must be in bitmap format. First, I render the SVG files to portable network graphics (.png) using inkscape. Inkscape provides some convenient command line options that allow just that. Inkscape allows me to export the SVG bounding box to a .png.
    • I wanted to have a very general way to do postprocessing on the icons, and found Imagemagick. Imagemagick is like a swiss knife of bitmap processing, and best of all it allows to specify all the operations programmatically. I know to some of you this doesn't sound very exciting, but that's usually because you don't fully realize what incredible possibilities Imagemagick has. It's quite hard to overestimate the awesomeness of Imagemagick! I use Imagemagick to automatically make the icon size 64x64, with the graphics nicely centered. (That is to say: the icons are only displayed at 48x48 right now, with the resizing done in Qt - I may revise these settings in the future. The nice thing about having everything automated is that it becomes easy to make experiments with different settings).
  • The build system: GNU make (for now). As I've used it before it seemed like the quickest way to get something. In retrospect, I probably should look out for something else. As I found out the hard way, GNU make has some serious trouble when it comes to dealing with filenames containing whitespace. It also is less than ideal for cross-platform development. Sure, there's a native win32 version of GNU make available, but one of the things bothers me is how its internal variable $(RM) on windows platforms still is defined as
    rm -f
    , making it harder than needed to implement a
    make clean
    on windows.

The code

The code can be found on http://speedsightread.sourceforge.net/. It also contains an .nsis file to generate a nullsoft installshield (setup.exe) for windows systems. The make clean target for now only works on linux systems. There are no pre-built versions available yet.

Building the code

  • To build the program you need: python 2.x (I used python 2.7), pyqt4, lilypond, imagemagick, GNU make
  • To build an installshield you additionally need: py2exe, nullsoft nsis
  • To run the program, once it's built, you only need python 2.x and pyqt4. If you build the windows setup.exe using the nullsoft nsis script, you don't need anything else but the setup.exe.

Current status

As usual with python based software, I got lots of result for a relatively small effort. It-works-for-me. No pre-built versions available yet. It remains to be seen if I can actually improve my sight reading skills using it :)

A final screenshot

Here's another screenshot, running on linux (icewm with an XP theme):

Friday, May 4, 2012

Pyjamas hijacked!

Image retreived from public-domain-image.com.

What is pyjamas?

Pyjamas is a port to python of google's web-toolkit (GWT). Pyjamas allows one to write python code, and have it automatically translated into javascript. The generated javascript then can be run inside a browser as a web application, or can be run unchanged in a suitable run-time environment as a desktop application. In both cases, the applications can communicate with web servers via AJAX calls.

What happened?

During a heated discussion about what it would take to promote pyjamas to a larger audience, some people got angry with pyjama's main developer and innovator, Luke Leighton. In summary, a few people were not happy with the existing infrastructure used by the project whereas the main developer rather bluntly dismissed the concerns and told people to concentrate on things that really matter instead. Furthermore, Luke told the people that pyjamas is bloody innovative. innovations are disruptive. get used to innovation being disruptive!. . People got really upset and concocted some sort of master plan to prove the world once and for all they were not to be laughed with. Innovation disruptive? They were going to teach Luke about innovation!
The normal procedure when people are not happy with the way an open source project is lead, is to create a fork and let both parties go their own way. This is more or less what happened here too, but with an evil twist (read on, stuff like this doesn't happen every day).
As it turns out Luke Leighton didn't hold the rights to the domain name pyjs.org, and the disgruntled people (at least one of which had admin rights on Luke's server to "help out" with administering it) contacted the rightful owner of the domain, and convinced him to transfer the domain name to the dissidents. Then, suddenly and out of the blue came an [[ANNOUNCEMENT]] on the (now defunct) pyjamas-devel mailing list (although to be honest there had been a vague hint to it in the past). In the announcement it was said how pyjs.org from now on points to a new location, where the pyjamas source code and wiki can be found on github, and the mailing list has been replaced with mailman3 software, and it was pointed out that Luke Leighton from now on was no longer in charge of the project in its new incarnation. Until today it's not entirely clear if private data has been copied from Luke's server to recreate the mailing list using new software. If that is indeed the case, it might consist of a criminal act (data theft) in at least one of the involved countries, and we may not yet have seen the last of this.

Effects of the hijacking

Well, the basic aim of the disgruntled people is to have better infrastructure, to make the project look more mature and attract more developers. How well did they succeed in achieving their goals with their actions? The current state of things for an outsider, at the time of writing 4 days after the facts, is not looking very good to say the least (although the dissidents, I'm sure, will disagree):
  • The new and "improved" website lacks basic functionality: most links are broken; the manual is offline; the examples are no longer accessible. Most links in google's archives now point to non-existing pages. Contact links still point to the old defunct mailing list, etc. I assume this will be solved over time, but in a proper transition to new infrastructure, this should have been solved before transitioning. Someone clearly was in a lot of haste to pull off this underhand trick, and apparently all this haste lead to getting very tired, too tired to fix the basic functionality. (And oh the irony of fate! While I'm writing this post, the google groups appear to suffer from very slow reply times. Seems like the shiny new technology has its share of flaws as well...)
  • During the recreation of the mailing list under the new ownership with new mailing list software, something went wrong and tens of people who had registered to the mailing list, but had asked not to receive emails (e.g. because they follow the group using an nntp reader via gmane) now suddenly got flooded with emails from the pyjamas list and started sending mails to unsubscribe (which were then received by all the other people who also didn't want to receive emails from the mailing list, who then also started to send unsubscribe mails...) The unsubscription emails didn't work, because the new mailing list software expects different commands (but of course no one had been informed about that), which led to an avalanche of "please unsubscribe me" and "please stop unsubscribing" messages, and eventually to killing off the mailing list, and creating a new one here. Looking at the number of people who've subscribed to the new list so far (5 at the time of writing, one of which already made it clear that he doesn't agree to how the changes had been hastily enforced), it would seem that this whole operation is not exactly something a 600+ community of people was waiting for.
  • Since the hijacking, only a few individuals have publicly applauded the event. So far, the hijack seems to have happened to serve the interests of those few individuals. No discussion about the matter happened on the mailing lists. No wonder a large part of the existing community is shocked and, frankly, pissed off (including, it seems, many of the current top committers). No matter how many professional tools one uses, without active committers the future of the project looks very uncertain. And with the main developer and innovator basically having been stabbed in the back, it can be expected that he won't be contributing to the project anymore (in the best case he would continue in a fork of his own, perhaps under a new name, but at this moment nothing's certain).
  • Corporate users of the framework now consider the whole project to be avoided-at-all-cost. No one in his right mind wants to base a business on a project hijacked by a minority of impulsive hotheads, without clear guarantees for continued development and support.

Conclusion

Even if the project manages to survive and attract new developers (and I really hope it does in one way or another, because pyjamas at its core is really cool technology!) the current state of matters where the main contributor and driving force Luke Leighton is as-good-as-eliminated from the project, where the fully functioning website is hastily replaced with something completely broken for days in a row and while making a significant part of the active and passive users unhappy is probably the worst possible thing that could have happened to it, and despite the new and shiny tools, the project might take a long time to reach a decent velocity, and gain some credibility with corporate users again.

EDITED TO ADD: shortly after publishing this blog entry, the copy of the pyjamas website has become more functional again. It was about time. EDITED A SECOND TIME TO ADD: see http://technogems.blogspot.com/2013/08/can-pyjamas-rise-from-its-ashes.html for a surprise :)

Saturday, March 24, 2012

Syntax highlighting stax scripts in vim

What is Staf/Stax?

STAF is a Software Testing Automation Framework. It provides all basic infrastructure for creating robust distributed test environments. It's structured as a collection of services which can be called from the command line or from a ui, or from your favourite programming language. These services implement things like: "start a process on pc xxx and get the return code", "copy files from pc xxx to pc yyy", synchronization primitives, sharing of variables between pcs, sending mails, etc etc etc.

STAF is a very impressive piece of software. Don't let the outdated JAVA ui look and feel of some of the tools that come with it fool you. Everything can be activated from the command line. Making use of the JAVA uis is optional, but the ui offers lots of out-of-the-box functionality that I wouldn't want to program myself if I can avoid it. Probably the quickest way to get started writing a test harness is to use the STAX service. Lots of excellent documentation and tutorials on STAF/STAX are available from the official STAF/STAX website, but I found it beneficial to first read this introduction from Grig Gheorghiu. STAX offers an XML based language with embedded Jython fragments (Jython is a version of Python that compiles to the java virtual machine).

To be honest, STAX being based on XML doesn't make it the most programmer friendly programming language in existence (the value of what it provides to a certain extent compensates for the discomfort of using it). To make it somewhat user friendlier, good syntax highlighting is indispensable. The syntax highlighting is somewhat complicated because STAX really consists of a combination of two rather different languages in one: on one hand there's the XML that is used to define the high-level control flow of the test harnass. On the other hand there's embedded jython code.

If you understand why creating a syntax highlighting definition for a language like STAX could be a challenge, you might appreciate the elegance with which the problem can be solved in the world's most powerful programmer's editor: vim. Vim offers ways to define syntax highlighting in different modes (if you know vim, this concept of modes should not come as a surprise ;) ). The easiest way to syntax highlight STAX programs in vim is to reuse the existing syntax highlighting for XML and Python. Vim can switch between different syntax highlighting modes based on encountering certain regular expressions.

Syntax highlighting code

Put the following code in a file called stax.vim:

runtime! syntax/xml.vim
unlet! b:current_syntax
syntax include @Python syntax/python.vim
syntax region pythoncode matchgroup=pythongroup start=+<script>+ keepend end=+</script>+ contains=@Python
hi link pythongroup xmlTag

On my linux system, in the .vimrc file, I added

au BufNewFile,BufRead *.stax set filetype=stax

to activate the syntax highlighting for all files that have a .stax file extension. On a windows system, i had to add the above line to "Program Files"\Vim\vim73\filetype.vim instead.

With the syntax highlighting definition provided here, STAX becomes more programmer friendly. (Note: I posted this same code some time ago on the staf/stax mailing list)

Monday, December 19, 2011

YouNeedTests: a python3 based C++ unit testing tool

(Image retrieved from http://blog.hinshelwood.com/. According to google image search this image is labeled for reuse. Please let me know if you disagree.)

Unit testing in C++

Perhaps you recognize the following story. You're finished writing C++ code, and now you want to add some unit tests, because it makes the metrics look good. You're using a well-established C++ unit testing framework, like CppUnit. Adding a new test requires manually adding files to the solution, adding seemingly duplicated information in .cpp and .h files (i.e. implementations and declarations) and invoking obscure macros. Or perhaps you copy an existing test file and start editing it to test new stuff. Or worse: you extend an existing test with some extra lines to avoid creating all the boilerplate code over and over again.

However, being a programmer and not a file copier, I would really appreciate if we could use our computer a bit more efficiently to specify tests.

YouNeedTests: Python3's doctest meets fitnesse for C++ code

doctest? fitnesse?

The brilliant thing about python's doctest module is how it extracts tests from comments embedded in the source code. This leads to executable documentation which by its very nature never needs to become outdated. Doctest is typically used to write unit tests: tests written by programmers for programmers, trying to test little bits of code in isolation.

The brilliant thing about fitnesse is how it specifies different test scenarios in table form. Fitnesse is typically used to define acceptance tests: tests written by business and QA people and intended for business and QA people. Acceptance tests usually involve more objects than unit tests.

requirements

I wanted a tool that could be used with C++, and that transforms comments embedded in the C++ code into unit tests. I also wanted a way to specify different test scenarios in table form. Because I prefer python over C++ in matters of text processing, I decided this was an ideal opportunity to wet my feet in several "hot" and "established" technologies:

  • git as source code management system. The brilliant thing about git is its distributed model, its insane flexibility, speed and compactness, and its superb support for branching and merging.
  • python3, the somewhat controversial, non-backward compatible successor to the very popular python2 language. I still have to find out what's so brilliant about python3 - but so far python3 hasn't been a negative experience.
  • yaml to format the comments from which the code will be generated. The brilliant thing about yaml is how it combines expressiveness of XML with a much more human friendly syntax. Human friendly enough that I didn't create a domain specific language to specify tests in.
  • googletest as backend unit testing framework. The brilliant thing about the googletest framework is how it requires fairly little boilerplate code to write simple tests. The second brilliant thing about googletest is that it supports death-tests, i.e. you can check if a piece of code crashes as expected.
  • CMake for the build system. The brilliant thing about CMake is how cross-platform, easy to use and versatile it is as a build system. It also comes with built-in provision for testing (and loads of stuff I haven't discovered yet).
  • mako to generate boiler plate code and build scripts. The brilliant thing about mako templates is their ease of use and the fast speeds with which they are rendered.

Example

Here's a simple comment that will 6 independent tests from a table of scenarios. Not all tests need to have a table, one can also embed raw code if desired. A comment like the above consists of several parts:
  • a testsuite name
  • a testsuite type: for now 3 types are supported:
    • COLUMNBASED: CODE section contains a list of tables. Each line in each table is an independent test.
    • ROWBASED: CODE section contains a list of tables. Each table becomes a test. Each line in a table is one step in the test.
    • RAW: CODE section contains normal C++ code.
  • a LINK section: this specifies which .cpp files should be linked in with the test
  • an INCLUDE section: this specifies which .h files to include in with the test
  • a STUBS section: this can contain arbitrary C++ code to resolve linker errors. Only stub those parts of the code which are not testing. There's no point in testing stubs :)
  • a PRE section: code in the PRE section is executed before anything from the table is execute
  • a POST section: code in the POST section is executed after executing statements from the table, but before executing assertions from the table
  • a CODE section. In case of a COLUMNBASED or ROWBASED test suite, the CODE section contains a list of tables. Each table has a table header that specifies code templates with placeholders $1, $2, .... The placeholders will be filled in with values from the table cells in the same column. Each table has a NULL column (the ~ symbol) which separates the statements on a line from the assertions.
    • The line containing the string 'twovalues' in table 'TABLE1', e.g. will result in the following lines of code being generated: where the double comma (",,") causes the code template to be unrolled. (Of course the system will also generate all the rest of the required boilerplate code and buildscripts, finally leading to this .cpp file (buildscript not shown here): Despite being used with a toy example, the table format already results in quite some space and boiler-plate reduction :)
All the generated tests can be run at once by issuing "make test" in the output folder:
More detailed test results are available by individually running tests:

Proof of concept code!

Got curious? Hop over to Gitorious! LGPL'd proof of concept code - for now I only tried to use it on debian sid amd64.

Monday, August 29, 2011

easy cross-platform inter process communication (IPC) between your program and swi-prolog

Image available under creative commons license from the Flickr photostream of DailyPic.


The problem

In this tutorial I will show how to set up communication between your program (can be written in any language) and swi-prolog. If you, like me, are using python, you might be tempted to use the python/swi-prolog bridge pySWIP, but it has a major disadvantage: it just doesn't work on 64-bit platforms (yet?). If you use any other language, your mileage may vary: e.g. in JAVA you will often be advised to use a prolog that runs on a JVM.

What is presented here is a slightly different approach, which works beautifully across platforms, operating systems and network boundaries. Moreover, it ensures that your prolog code remains very well separated from your main program's code, which cannot be a bad thing.

This tutorial explains matters from the point of view of talking from a python program to a prolog backend.

Nothing prevents you from talking from a prolog frontend to a python backend. The prolog predicates required to do so are not explained in this tutorial (you can read about it in the manual of swi-prolog, in the part about http/http_client)

Approach


Swi-prolog makes it quite easy to write a web service. Swi-prolog also has built-in support for JSON-RPC. By tying together those two functionalities we can interrogate the prolog backend using JSON-RPC requests.

Details


We want to keep it simple for the sake of clarity so we set out to achieve the following goal: a python program will communicate with prolog to calculate the sum of two numbers.

In order to do this we need two things:

  • a prolog program that implements some functionality in prolog and that also responds to JSON-RPC requests (i.e. a JSON-RPC server)
  • a client program that can talk JSON-RPC with our prolog server, and understands its replies (we will create one in python for the sake of simplicity).


Create a python client


After installing jsonrpclib, communication with a JSON-RPC web service is incredibly easy.


First an object is created that represents the server. Here it is assumed that the prolog JSON-RPC server will be running on localhost, port 5000, and it will respond to JSON-RPC requests at url http://localhost:5000/handle.

Once this server proxy is created, one can call methods on it. Here we ask the server to give back the result of "add(5,6)". The jsonrpclib library will automagically convert this method call into a JSON-RPC request, send it to the web-server, read the reply, unparse it from JSON back to python, and return the result. How's that for cool? ;)

If you use another programming language, you will most likely be able to find some specialized library to work with JSON-RPC.

Creating a prolog JSON-RPC server


The prolog JSON-RPC web service isn't that much harder to understand too.
First we import a bunch of libraries that provide much of the required functionality in creating web services out of the box.

Then we get

This line tells prolog that the predicate handle_rpc will be executed (it implicitly assumes that handle_rpc will take a Request as parameter) whenever someone visits the url handle (as indicated by the root(handle) part of the line). Note: nothing prevents you from handling url handle by a predicate with the same name. I gave them different names here (handle and handle_rpc) to make it more explicit in which ways the parameters of http_handler are used.

The next line
http_json:json_type('application/json-rpc').
tells prolog that 'application/json-rpc' is a valid mime-type for a JSON-RPC request. As it turns out, the built-in JSON-RPC support by default only recognizes mime-types of 'application/jsonrequest' and 'application/json'. 'application/json' is the suggested mime-type adopted by RFC4627. The python client, on the other hand uses 'application/json-rpc'. Luckily the makers of swi-prolog decided to make the http_json:json_type predicate a multifile predicate, meaning that it can be extended outside its original file (in other words: by us, the user of the library). If you don't allow 'application/json-rpc' as a valid mime type on the server, the python client will keep receiving an "500 Internal server error" error.

The lines

configure a web server on port Port. After starting prolog, and consulting your prolog server file, you can start the web server on port 5000 by evaluating the following goal:

This will spawn some threads and immediately return to the console prompt, which opens up possibilities for debugging your web service (read more about these possibilities in the HOWTO part of the swi-prolog documentation).

Then comes the handling of the request:


First the json is extracted from the Request, and read into a variable JSONIn.
The http_read_json predicate is provided by the http/http_json library included with swi-prolog. Next, the JSONIn variable (which is basically a string; a datatype described in a subset of javascript) is parsed into a prolog data type. The json_to_prolog predicate is provided by the http/json_convert library included with swi-prolog. After that we evaluate the contents of PrologIn, and from that create PrologOut. Using the current sample code json_to_prolog won't do anything. It can be used to automatically convert the prolog representation of the json reply into a more "prologic" form. To make this magic possible, one needs to declare json_objects. Using prolog_to_json, PrologOut is converted to a more "JSONic" prolog term again, and then sent back to the client with reply_json. This conversion relies on the same json_object declarations as json_to_prolog. For now I don't fully see the advantages of this process. Please chime in, if you have more insights. prolog_to_json is provided by the http/json_convert library.

The evaluate predicate is one we have to write ourselves. It's where the computations take place that are needed to handle the request (in our case: the addition of two numbers). Here's how the evaluate predicate works:
A json request consists of predefined fields:

  • jsonrpc: A String specifying the version of the JSON-RPC protocol. MUST be exactly "2.0".
  • method: A String containing the name of the method to be invoked. Method names that begin with the word rpc followed by a period character (U+002E or ASCII 46) are reserved for rpc-internal methods and extensions and MUST NOT be used for anything else.
  • params : A Structured value that holds the parameter values to be used during the invocation of the method. This member MAY be omitted.
  • id : An identifier established by the Client that MUST contain a String, Number, or NULL value if included. If it is not included it is assumed to be a notification. The value SHOULD normally not be Null and Numbers SHOULD NOT contain fractional parts. The id is sent by the client, and should be sent back with the response so the client knows what query is being answered.


More specifically, if we use our python client, after translation to prolog, we get the following term for PrologIn:

We unify it to extract the parameter values, id, and method:


Note that in its current form, the prolog web service is rather inflexible: it will just know how to do an "add" of two numbers. I'll leave it up to your imagination to see how this can be generalized or abstracted.

A JSON-RPC response also has a predefined format. It contains the following fields:

  • jsonrpc: A String specifying the version of the JSON-RPC protocol. MUST be exactly "2.0".
  • result: This member is REQUIRED on success. This member MUST NOT exist if there was an error invoking the method. The value of this member is determined by the method invoked on the Server.
  • error: This member is REQUIRED on error. This member MUST NOT exist if there was no error triggered during invocation. The value for this member MUST follow some predefined rules (see JSON-RPC specification for details).
  • id : This member is REQUIRED. It MUST be the same as the value of the id member in the Request Object. If there was an error in detecting the id in the Request object (e.g. Parse error/Invalid Request), it MUST be Null.


So we are ready to calculate and formulate our reply:


The MethodName = add just verifies that we really were asked to do an add on two numbers.
The Sum = Param1 + Param2 performs the calculation, and
the PrologOut contains the reply that will be sent back to the client.

Running the programs


The hard work is done. Now we can enjoy the fruits of our labour:
Start a console (dos prompt) and start the prolog server on port 5000:

swipl -f server.pl -g "server(5000)."

Start a second console and run the python program:
python rpc.py

If all went well, running the python program should print:
The result is: 11

To kill the prolog server, you can manually type
halt.
on its console prompt, but you could of course also design an RPC request that tells the interpreter to shut itself down.

Your imagination is the only limiting factor.


Friday, April 29, 2011

Code available!


The code so far can be found in SVN on Sourceforge.
It does something already, but is not ready for release yet.

Sunday, April 17, 2011

C/C++ include file resolution


Another why-oh-why experience today. I'm trying to find out how the preprocessor is resolving include files, like: what paths will be searched first.

I expected the following behaviour:
  • #include <somefile.h> : only search the paths that were passed to the compiler using the -I switch
  • #include "somefile.h" : first search the folder in which the file being examined lives, only then start searching the folders passed to the compiler using -I.
Instead I found that the behaviour is compiler dependendent (hence the why-oh-why?!) According to this article:
  • the #include <somefile.h> variant:

    StepVisual studio GCC
    1 paths passed by /I paths passed by -I
    2 paths specified in INCLUDE environment variable system directories
  • the #include "somefile.h" variant

    StepVisual studio GCC
    1 the same directory as the file that contains the #include statement the same directory as the file that contains the #include statement
    2 the directories of any previously opened include files in the reverse order in which they were opened directories passed in by the -iquote option
    3 paths passed by /I inside the quote directories
    4 paths in the INCLUDE environment variable
To clarify the "inside the quotes" method: for example if /usr/include/sys/stat.h contains #include "types.h", GCC looks for types.h first in /usr/include/sys, then in its usual search path. So what now? Do we really need separate project resolution algorithms that mimick these approaches? Since I'm not trying to keep the tool's command line options compatible with those of the compiler, I think I can get away with a simpler scheme (counter examples are welcome of course). For now include files will be resolved as follows:
  • Step 1: check the folder of the file being examined (only if the "" style of include was used)
  • Step 2: check the include folders that were passed to the tool using -I like options (in the order in which they were passed in)

Wednesday, April 13, 2011

Cross-platform file name handling


The challenge

On many operating systems file names are case sensitive. The windows OS, however, has case insensitive file names. The tool preferably should be cross-platform, which in my opinion means that we should be able to analyze:

  • code written on a linux system with a tool running under windows
  • code written on a linux system with a tool running under linux
  • code written on a windows system with a tool running under windows
  • code written on a windows system with a tool running under linux

The first option is not possible in the most general case. In linux it would be perfectly possible to have two different files in the same folder: includeme.h and IncludeMe.h. On windows those two would be the same file. Too bad, nothing we can do about it. The second option also presents no problems.

The headache starts when trying to implement scenarios 3 and 4. Code written on windows systems tends to be rather sloppy when it comes to specifying include files. The compiler certainly won't enforce using correct case for file names, and writing


on windows means exactly the same as writing:


The approach

To be able to handle all four scenarios transparantly, I have opted to add a command-line option to the tool to explicitly inform it about the required case sensitivity mode of operation. File names are wrapped in a FileNode object that always holds the case sensitive file name (including full path).

The FileNode object then exposes two methods: file_name (which returns the case sensitive name), and analysis_name which, for the case insensitive operation mode, is the all-lowercase version of the file, and for case sensitive operation mode is the case sensitive version of the file name, possibly truncated to a maximum length (no one wants to write queries involving a file name like /home/username/development/cpp/largeproject/library/sublibrary/longfilename.cpp, right?)


Apparently path.py only recognizes os.sep as path separator. This makes it a bit harder to analyze windows software, where both forward slash / and backslash \ are valid path separators. Path.py seems to only recognize \ on windows and / on linux. This issue explains the kludgy lines where path separators are replaced at the top of method FileNode.__pp(self, for_display).
To make the tool work cross-platform as defined in this post, we pass the allowed path separators into the tool via a command line option.